evaltrack examples
Small, runnable evals that double as documentation. Each file is a self-contained pytest module with
the @pytest.mark.evaltrack marker. Every example runs offline. The models and judges are scripted,
so no API key is needed.
uv run --with pytest-asyncio pytest examples/   # examples 1 to 6 are async tests
uv run evaltrack ui                             # open the dashboard on the recorded runs
To run one example, give its path instead of examples/.
| File | Shows |
|---|---|
test_01_function.py |
The parts of an eval on a plain function: a task, cases, an evaluator, and the marker's gate. |
test_02_scores.py |
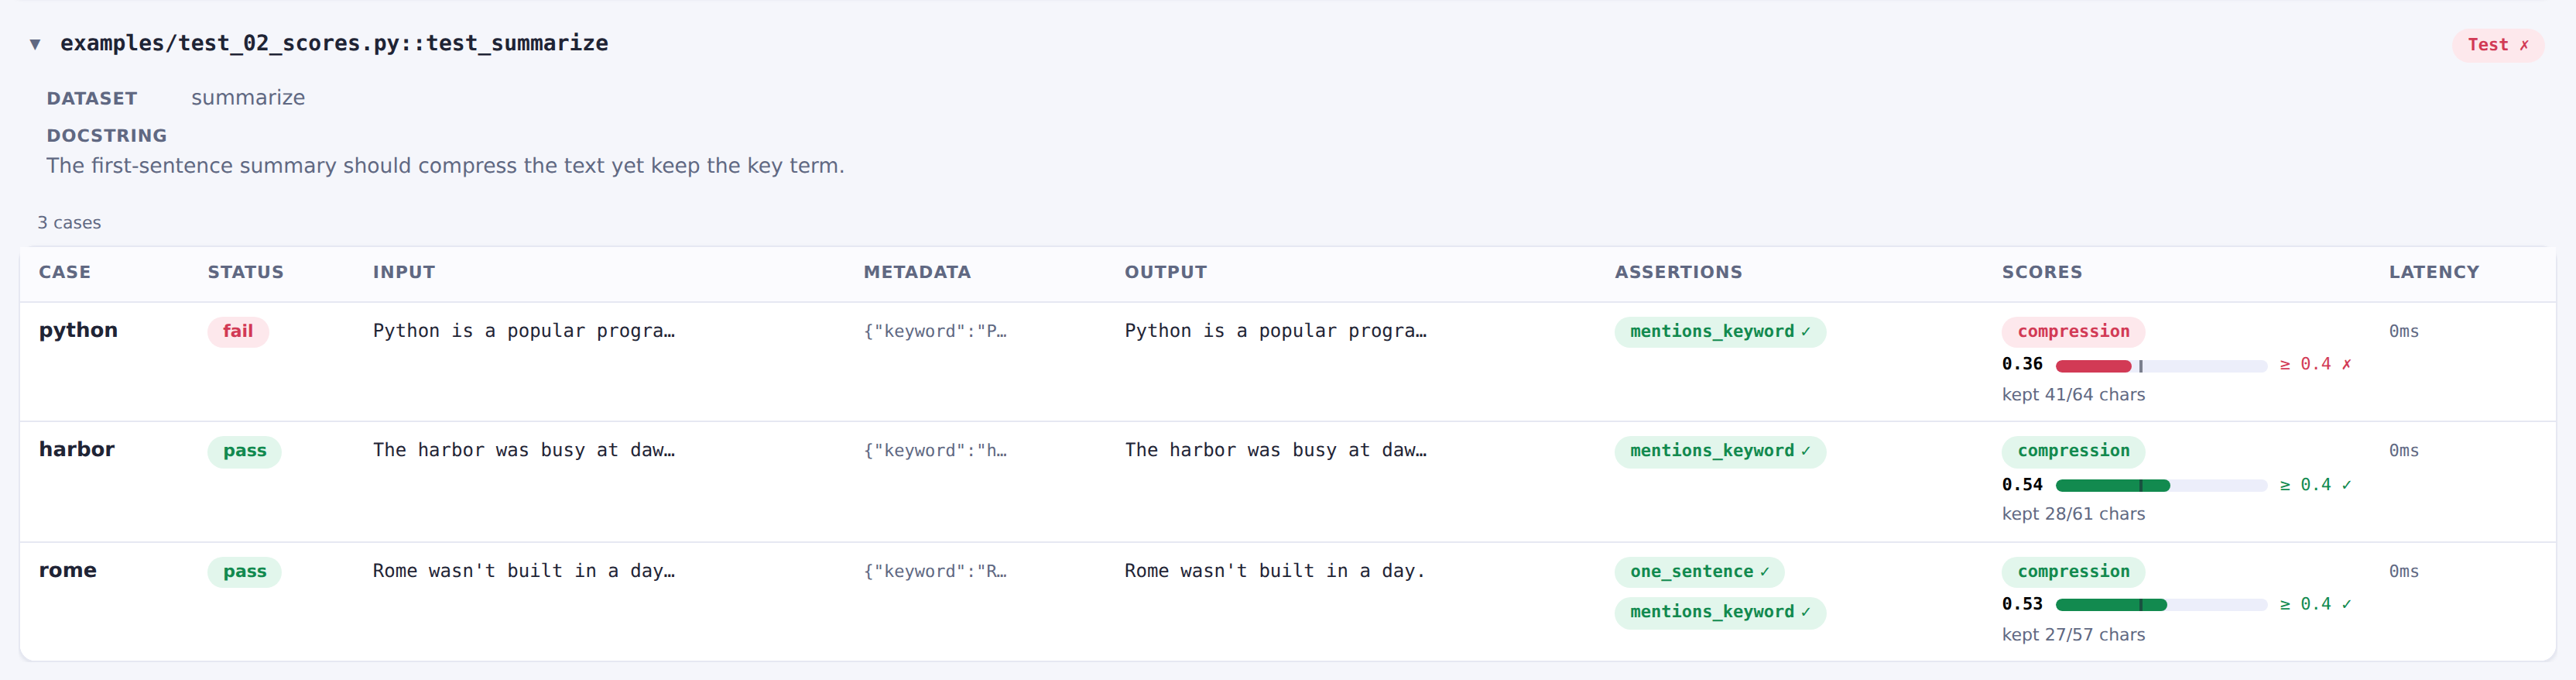
Scores and score_bars, evaluators on the dataset or on one case, and Case.metadata. |
test_03_reliability.py |
A flaky case absorbed by flake_reruns, with reliability_target and eval_version. |
test_04_agent_tool_use.py |
An agent that must call its tool only when the question needs it. |
test_05_llm_judge.py |
An LLM judge as a must-pass assertion and as a score gated by score_bars. One case fails on purpose. |
test_06_fake_tool_in_inputs.py |
A faked tool's documents put in Case.inputs, so the run shows what the agent could search. |
test_07_deepeval.py |
A DeepEval evaluate() recorded and gated. A metric's threshold is its bar, and score_bars gives a bar to one without. |
test_08_deepeval_repeats.py |
repeats=N over DeepEval, which has no repeat of its own. One case fails a round, so the test fails. |
test_09_other_eval_runner.py |
A translator for a runner evaltrack does not know, registered from the test file. |
Evaluating agents
Examples 4 to 6 evaluate pydantic-ai agents. evaltrack does not require
pydantic-ai, and pydantic-evals evaluates any callable. The agent, its tools, the dataset and the
evaluators are what you write for a real model. Only the model is a stand-in, a
FunctionModel with scripted replies. In example 5, the judge
is one too.
To run one against a real model, pass a model string such as "openai:gpt-4o-mini" to Agent(...).
In example 5, pass it to LLMJudge(model=...) too. Then remove the ALLOW_MODEL_REQUESTS = False
line and set the provider's key:
uv sync                  # the dev group includes pydantic-ai-slim[openai]
export OPENAI_API_KEY=sk-...
In the dashboard
evaltrack ui shows each run with its per-case verdicts, scores, and the test docstring as context.
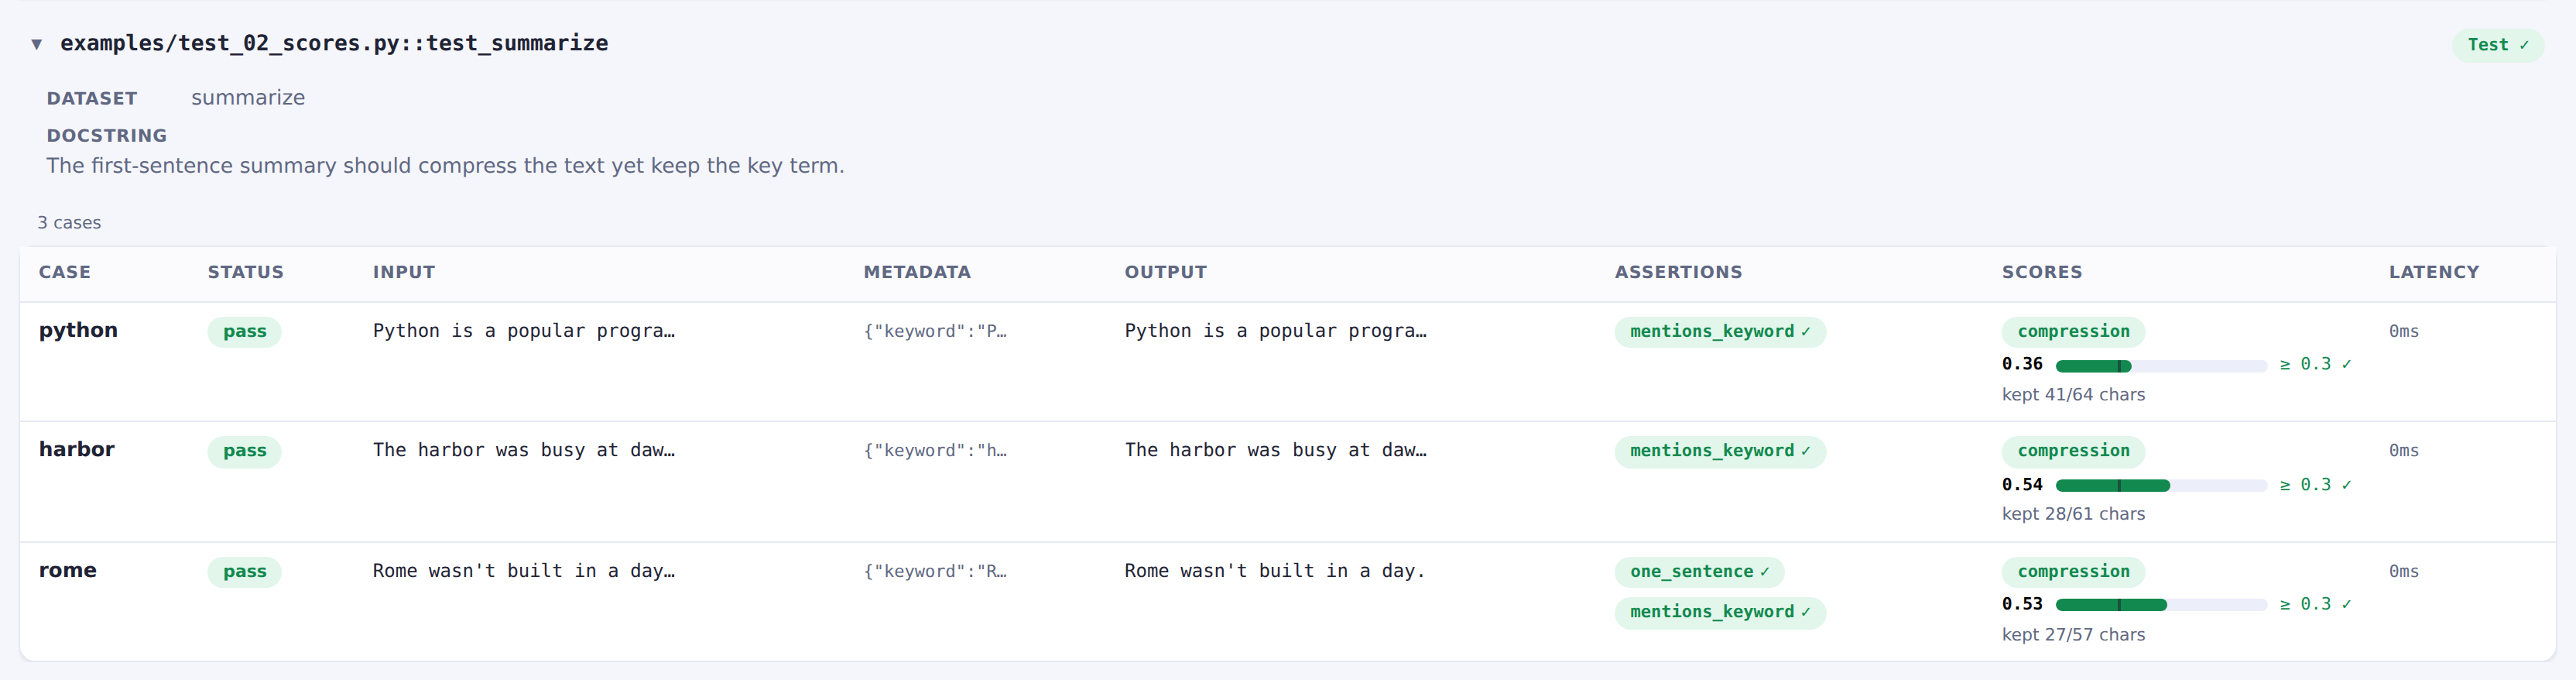
Examples 5, 8 and 9 fail on purpose and carry an xfail mark, so the suite stays green. To see a
failure in the others, raise a score_bars bar or change a case's expected value.